Today, rising amounts of documents and the contained information have to be processed by enterprises to be able to use the hidden content. This is either done by time-expensive manual text summarization or by using an automatization solution. Automatic text summarization helps humans to efficiently process the growing volume of information.
What exactly is automatic text summarization?
The Oxford English Dictionary defines automatic text summarization as "the creation of an abridged version of a text by a computer program. The product of this process still contains the main points of the original text." [1]
A good example where summarization can be useful is the annual reports of companies. Those documents contain a lot of facts that can be crucial for investors since they include information on many factors such as sustainability or environmental policies which can help the investors' decision. However, the annual reports are normally very long documents with hundreds of pages, which makes their analysis a time-consuming process that could be facilitated by an automatic workflow.
How can we summarize text in PDF files?
We divide the process into three main parts. For each of those steps, we go more into detail in the following sections of this article. Feel free to jump right into the details or let us first walk you through the main outcomes of each step.
1. Use Object Detection for Page Segmentation
In the first step, we need to select those parts of the document that have to be focused on. With page segmentation or also called layout analysis, we refer to the division of a document into separate parts. This is done with our own trained model because we couldn't achieve the needed outcome with off-the-shelf software like Tesseract or Abbyy FineReader. While we can get a lot of already summarized information from images, graphs, and headlines, it is the text that is the most complete source of information. A possible way to split the document into different components is to use a computer vision approach. A model for multiclass object detection can automatically differentiate between different elements in the annual report. All content can be split into five categories: title, text, table, list, and figure. Only the found locations of the category text are used for the following steps of the summarization process.
2. Use OCR to convert the image to text
The next step is to convert the selected bounding boxes of the document into text. This part can be defined as an optical character recognition (OCR) problem, which was resolved using established tools. Of course, this step can be omitted if the documents already have text embeddings. However, it is often necessary to read tables or scanned documents, for example. In our software solution, the users can decide for any project if they want to use text embeddings, Tesseract, or a commercial OCR.
3. Text Summarization of any paragraph
The final step is the summarization of the selected content. So-called Transformers, which lately have proven to be powerful models, come to play. We used the tailored BERT model PEGASUS which is specially designed for automatic summarization. The outcome shows us a summarized version of the paragraph that we detected and extracted from the report in the first steps. The original length of 910 characters was reduced to 193 characters, leading to a time saving of almost 80%. Still, all the relevant information to understand the paragraph is included.
This approach shrinks paragraphs in a PDF file by 80 %.
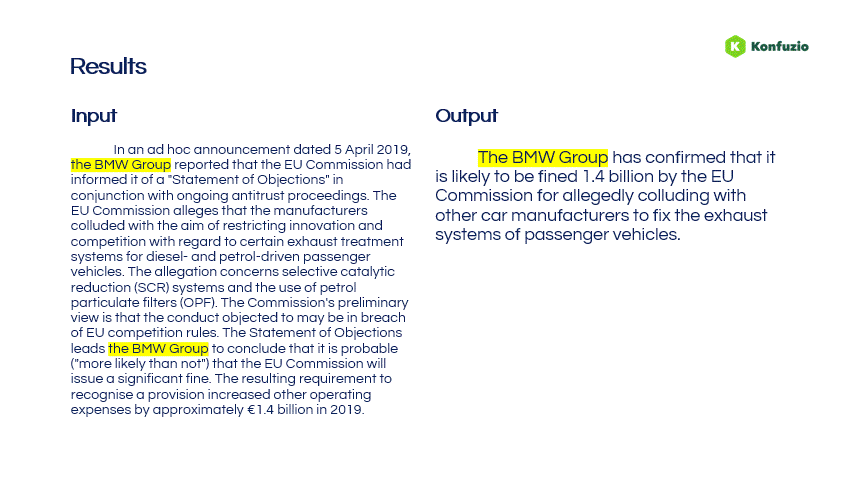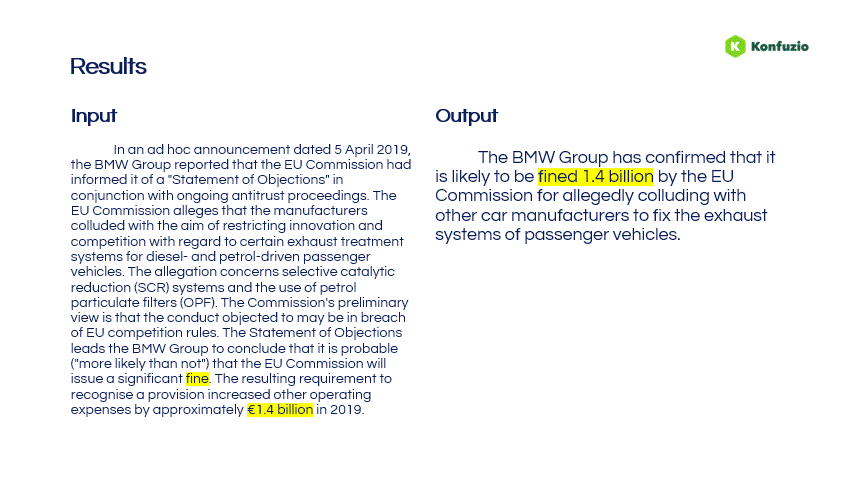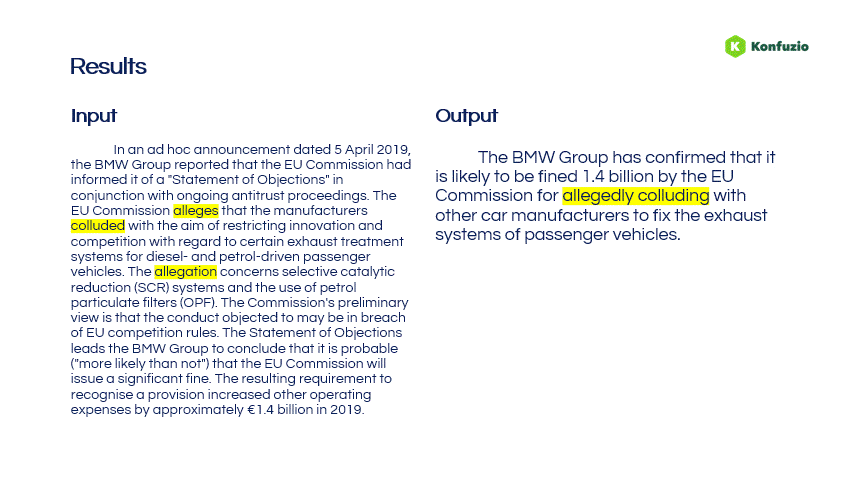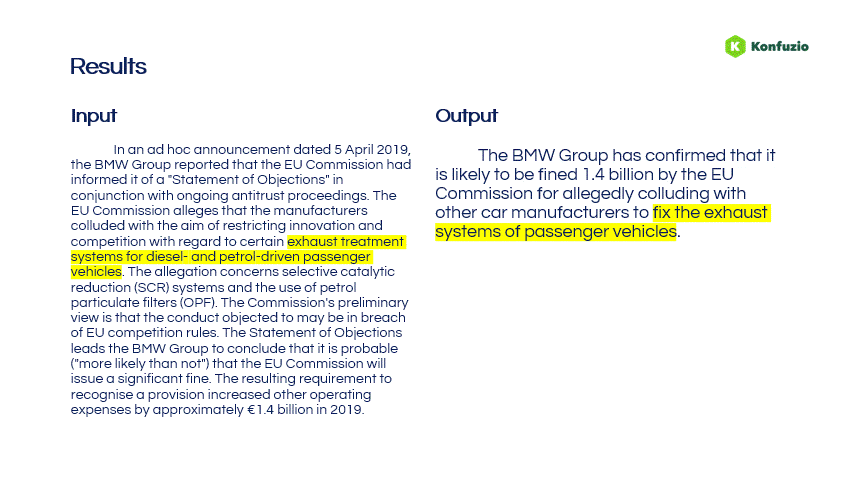
The result of the automatic text summarization with the PEGASUS model of one paragraph extracted from the annual report shows us a good result. Let’s step through it to check what kind of aspects are included: name of the company, likelihood of an event, amount of the fine, name of the commission.
Text Summarization with PEGASUS and Faster R-CNN Whitepaper
I agree to the data protection conditions by sending this form.

Do you want to learn more right now?
How to use object detection for page segmentation?
Object detection is a task where objects of a known class are identified in the image and information about its location is provided. A very known architecture for this task is the Faster R-CNN. This architecture has two outputs for each object: a class label and a bounding-box. It consists of two modules: one deep fully convolutional network to propose regions and a Fast R-CNN that detects objects in those regions.

The way that works is that an input image is fed to a convolutional network that provides a feature map of that image. Then, a separated network (the region proposal network) takes that feature map and predicts possible regions for the objects (region proposals). Those region proposals are fed to a ROI pooling layer that reshapes them into a predefined size. Finally, the output vector from the pooling layer is used to classify the proposed regions and to refine the bounding boxes.
More recently, Mask R-CNN, which is an extension of the Faster R-CNN, added a third output that allows having the mask of the object. This results in having the classification, bounding box and the mask of the object. The mask prediction is done in parallel with predicting the class and the bounding box [2].

The goal is to select only the relevant parts of the report, in our case the text paragraphs. Other parts that already contain summaries, like headings or tables, are not relevant. So the first thing we need is an annotated dataset containing the various document elements. PubLayNet is a dataset with annotations of text, figures, titles, lists and tables on more than 360,000 pages of scientific papers [3]. By fine-tuning a mask-R-CNN model trained on PubLayNet, we obtain a model that allows us to recognize the parts of the documents that correspond to the text. The model we used is available in the Detectron2 platform, a platform from Facebook AI Research that enables rapid testing of state-of-the-art algorithms [4]. In the figure, we can see the bounding boxes and the classification shown with a different colour for each class, which was the result without any fine-tuning. For our problem, we are not interested in the mask of the text, but only in the bounding box marked in blue.
Register for free and try out the page segmentation API with your own documents. Register to access our API documentation. Using our document labelling tool you can create a dataset and fine-tune the PubLayNet model on your own documents.

Which is the best OCR engine?
After having found the portion of the images that we are interested in, the next step is to extract the text from them with the use of optical character recognition (OCR). OCR can be done by computer vision approaches that can include detection, segmentation and recognition of characters but most recent approaches include a combination of CNNs and Recurrent Neural Networks.
An example of a OCR pipeline can be:
- Text recognition - recognizes where the characters are located
- Pre-processing - the text is normalized
- Feature extraction - the output is the feature map of the image
- Post-processing - errors can be corrected, e.g. by comparing with more frequent word sequences.
How does text summary work?
Summarization is now commonly performed using Transformer models. Transformers are a type of neural network architecture introduced in 2017. They were initially designed for machine translation, but are now used for almost all modern NLP applications, such as entity recognition, natural language inference, question answering and summarization. Transformers are able to process all incoming data in parallel, in comparison to the previous state-of-the-art models, LSTMs, which processed data sequentially. This ability for parallelization makes them easier to scale up with an exponentially growing amount of compute and data.
The most important new concept introduced in the Transformer architecture is the use of "multi-head attention". In the Transformer, each element in the input sequence is divided into three vectors: Q, K and V. Attention is computed as a weighted sum of these vectors, where the weights are both learned and context-dependent. In other words, the data input to the model determines where the model should focus its attention. Multi-headed attention means that we split each vector into multiple "heads" and compute the attention for each head in parallel. We therefore perform several attention calculations at once, all in parallel, before merging the results at the output. [5]
The most commonly used Transformer variant is called BERT. BERT uses only the encoder from the original Transformer with very minor changes to the architecture. The main innovation of BERT is that it has been trained as a "masked language model" on a large amount of unlabeled text. Masked language models have the task of filling in the blanks of a given sentence, i.e. they replace some of the words in a sentence with a [MASK] token and then try to predict what the actual word was. This task has been found to teach the model a lot about natural language, so much so that it is now common to take a pre-trained BERT model and then tune it to the desired task. This is usually a good starting point when trying out neural networks for NLP, and most NLP research now focuses on how to improve Transformer models and their variants by either optimizing the architecture or inventing a new pre-training target.
PEGASUS is a model designed for automatic summarization. The architecture is similar to the original Transformer, with the decoder, but it is pre-trained on two tasks simultaneously. The first task is the masked language modelling task introduced by BERT. The second task involves predicting an entire sentence that has been masked out in the input. PEGASUS is first pre-trained trained on a huge amount of text, consisting of 1.5 billion news articles and then fine-tuned on the target dataset. It achieved state-of-the-art performance across twelve commonly used summarization datasets. [6].
Sources:
[1] He, K. et al. (2017). Mask R-CNN. Facebook AI Research (FAIR).
[4] Yuxin Wu, et al (2019). Detectron2 Github Repository.
[5] Vaswani, A. et al. (2017). Attention is all you need.

 EN
 DE
 ES
 FR